Reasoning
Similarity Arrangement Task
Also called: multi-arrangement, multiple arrangement task, spatial arrangement method, inverse MDS, inverse multidimensional scaling, similarity judgments
Measure how people see scenes as alike or different: participants drag 16 scene photographs around a circle by similarity, then arrange chosen subsets, by mouse, touch or keyboard.
6-10 minUntimed
Free to start: 10 free participants per account, then $0.99 per participant for academic research, or any yearly plan. Try it here first, with no account.
- Papers, 2021 to 2025
- 37
- Evidence grade
- C
- Registered clinical studies
- 0
What it measures
Measures how people see scenes as alike or different. Participants drag 16 scene photographs around a circle so that alike ones sit close and different ones far apart, first all of them and then a few at a time, by mouse, touch or keyboard. Scores each pair's distance, how closely the distances follow the kinds of scene and how well a person's map agrees with the study's other participants.
Constructs
- Perceived similarity
- Scene categorization
- Representational structure
- Individual differences in similarity
Research uses
- Similarity and categorization research
- Comparing people's maps with models
- Within-study group comparison
- Scene perception research
How the paradigm works
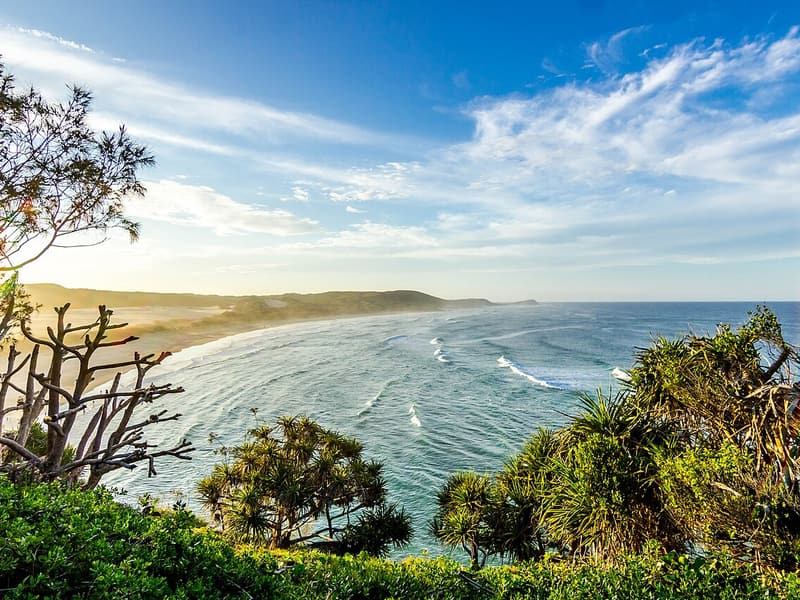
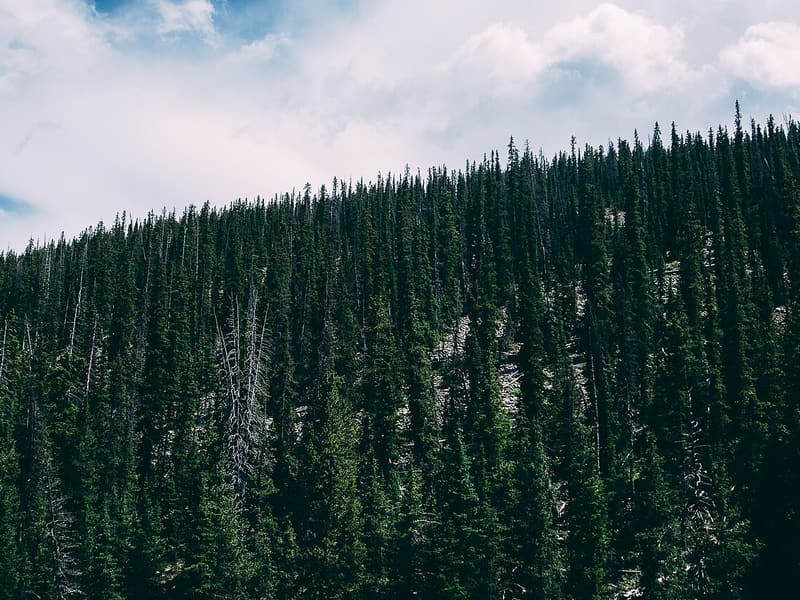
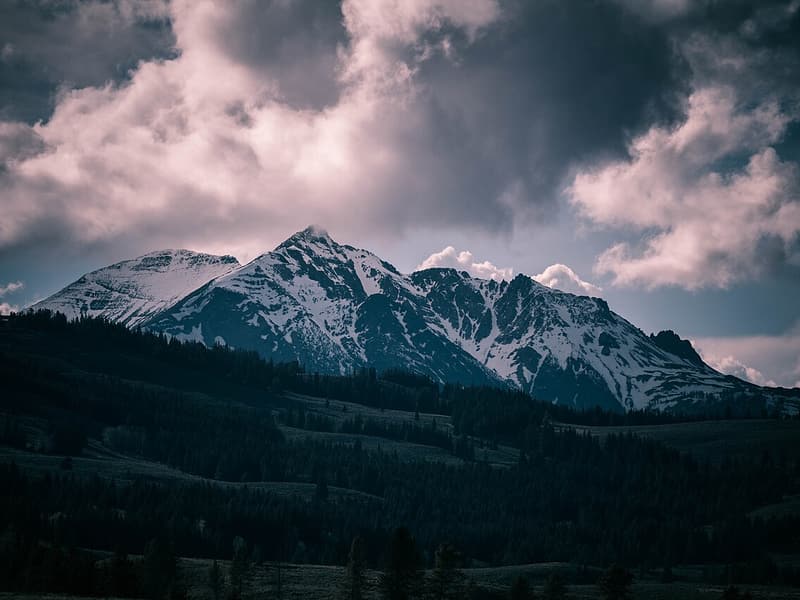
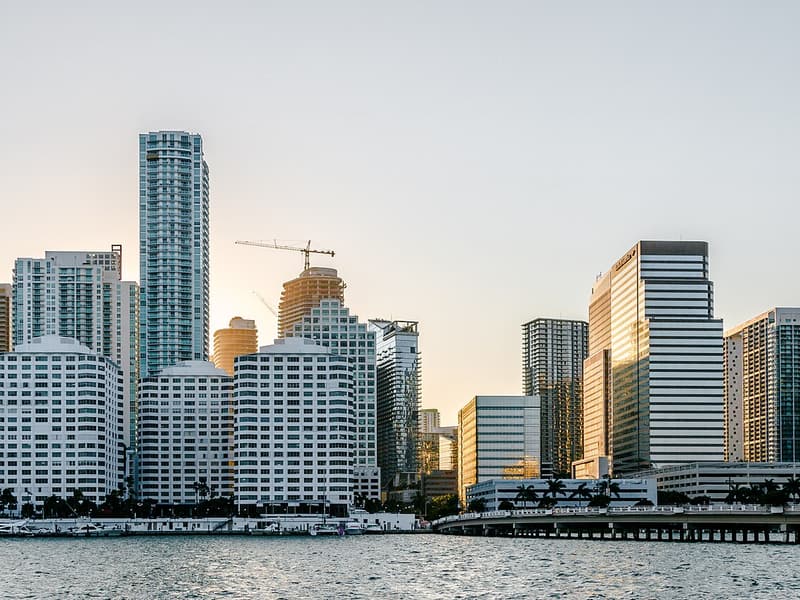
The Similarity Arrangement Task asks how a person sees a set of scenes as alike or different, by letting them place the scenes in a circle. The first board shows 16 photographs, two each of a coast, forest, mountain, desert, tall buildings, bridge, road and town, in a ring near the circle's edge in an order drawn for each session. The participant drags each one into the circle, by mouse or touch, by tapping it and then the circle, or with the keyboard, so that alike pictures sit close together and different ones far apart; Done works once every picture has been moved. Each later board holds 3 to 8 pictures, chosen from the person's earlier boards as the ones whose distances are the least certain, and the person arranges them again using the whole circle. Six boards (standard; 3 to 8) take about 6 to 10 minutes after a practice board of 4 pictures. There is no time limit and no right arrangement.
Scores
- Kind Fitscore
- Spearman rank correlation between the 120 distances and the pictures' scene kinds: 0 for one kind, 1 for two natural or two built kinds, 2 for natural against built.
- Informational; from -1 to 1, higher means the distances follow the kinds more closely; neither end is better
- Natural or Built Fitscore
- Spearman rank correlation between the distances and natural against built alone.
- Informational; higher means natural and built pictures are kept apart
- Consistencyscore
- Spearman rank correlation between the distances of the first board and those of the later boards, over the pairs on both; empty with fewer than 10 such pairs.
- Informational; higher means the later boards repeated the first board's pattern
- Study Agreementscore
- After the study closes: Spearman rank correlation of the person's distances with the mean distances of the study's other participants.
- Informational; empty with fewer than two other participants
- Pairs in the Agreementcount
- Pairs of pictures that the person and at least two others have a distance for.
- Informational
- Comparison Peoplecount
- Other participants whose distances the agreement used.
- Informational
- Boardscount
- Test boards finished, the first with all 16 pictures.
- Fewer than planned is flagged
- Planned Boardscount
- Boards the run planned.
- Informational
- Pairs on Two Boardscount
- Pairs of pictures that were on at least two boards, of 120.
- Informational
- Weakest Evidencescore
- The least evidence any pair has: the sum over boards of its distance in circle widths, squared.
- Informational; 0.5 and above settles a pair
- Arranging Timems
- Time from the boards appearing to Done, summed over the test boards.
- Informational
- Movesmoves
- Pictures moved, a picture moved twice counted twice, over the test boards.
- Informational
Use and evidence
37 papers from 2021 to 2025 name this task in their title or abstract, up 61% compared with 2016 to 2020. That ranks it 519 of 711 test families in our census. See the counts for every test.
Show the numbers
| Year | Papers |
|---|---|
| 2025 | 9 |
| 2024 | 6 |
| 2023 | 6 |
| 2022 | 8 |
| 2021 | 8 |
| 2020 | 6 |
| 2019 | 5 |
| 2018 | 4 |
| 2017 | 2 |
| 2016 | 6 |
| 2015 | 1 |
| 2014 | 1 |
| 2013 | 1 |
| 2012 | 2 |
| 2011 | 2 |
| 2010 | 2 |
| 2009 | 3 |
| 2008 | 4 |
| 2007 | 0 |
| 2006 | 1 |
| 2005 | 1 |
| 2004 | 1 |
| 2003 | 1 |
| 2002 | 3 |
| 2001 | 0 |
| 2000 | 0 |
Use grade D
30 to 99 papers from 2021 to 2025.
Evidence grade C
At least 2 test-retest papers, 30 reliability or validity papers or 3 registered clinical studies.
- Papers on test-retest reliability
- 2
- Papers on reliability or validity
- 19
- Registered clinical studies using it as an outcome
- 0
Measured on ConductCognition
Pooled across the studies that feed our platform norms, by device group. A figure needs 50 or more people.
No pooled figure yet.
How the grades work
Use: A is 1,000 or more papers from 2021 to 2025, B 300 to 999, C 100 to 299, D 30 to 99 and E fewer than 30. Evidence: A means at least 25 papers report its test-retest reliability and at least 25 registered clinical studies use it as an outcome; B, at least 8 test-retest papers, and either 5 registered clinical studies or 150 reliability or validity papers; C, at least 2 test-retest papers, 30 reliability or validity papers or 3 registered clinical studies; D, little published measurement evidence found. The counts measure use. They include every paper that names the task in its title or abstract. Grades describe the published research on this task, not ConductCognition's version of it.
Source: ConductCognition test census 0.58.0, counted 16 November 2026 from OpenAlex and ClinicalTrials.gov.
Task design
The trial sequence as the test runs in ConductCognition.
- Pictures
- 16 CC0 scene photographs credited on the terms page, two each of eight kinds: coast, forest, mountain, desert, tall buildings, bridge, road and town. No person is the subject, and none is a photograph the Scene Glimpse Task shows.
- Boards
- A practice board of 4 pictures, then 6 boards (standard; 3 to 8). The first holds all 16 pictures, spaced evenly near the edge of a circle in an order drawn for each session. Each later board holds 3 to 8 pictures chosen from the person's own earlier boards: those whose distances are the least certain.
- Moving
- A picture moves by a drag, by a tap and then a tap in the circle, or with Tab, Enter and the arrow keys. Done works once every picture has been moved. No time limit.
- Distances
- A pair counts on a board in proportion to the square of its distance in circle widths. The distances of all boards are put on one scale and averaged by those weights, which gives each person 120 distances with root mean square 1.
- Scores
- The 120 distances; how closely they follow the scene kinds and natural against built; how consistent the first board is with the later ones; and, once a study closes, the person's agreement with the study's other participants.
No arrangement is right or better, so no percentile is computed. The scores describe how a person arranged these scenes and support research; they do not diagnose.
Quality checks
Each session is marked valid, needs review or invalid, with the reason, before you see its scores.
Scored rows: the similarity_arrangement_board rows of the scored run, one board each with every picture's place in the circle. An arrangement has no correct answer, so accuracy is not judged against chance. A first board that is missing, or has fewer than all 16 pictures placed, invalidates. A run that ended before its planned boards, and distances missing for some pairs, are flagged. Boards finished under 200 ms per picture, for at least half the boards, invalidate.
Why these rules
There is no correct option to compare with chance, so accuracy is not judged against chance. A first board without all the pictures leaves pairs with no distance, so there is no map to read. The distances are scored from the places pictures were left in, so a board finished in a fraction of a second per picture was not arranged. An answer under 200 ms is faster than a simple visual reaction, so it cannot reflect the item. Following response-time effort screening for untimed tests (Wise and Kong 2005), the session is invalid only when at least half the answers are that fast.
No percentile. Scores and quality flags only.
Running this test
Settings you can change
| Setting | Standard | Allowed |
|---|---|---|
| Boards | 6 | 3 to 8 |
Yearly plans can change settings within these limits. Free and pay-as-you-go studies use the standard settings.
Need a setting this test does not have?
Devices and languages
- Untimed test: runs on desktops, laptops, tablets and phones. Participant devices
- Languages: English, Spanish, French, German, Italian, Portuguese (Brazil), Chinese (Simplified) and Japanese.
- Available on: Every plan, including the free plan.
- No percentile. Scores and quality flags only. How norms work
- Recruiting online? See the setup guides for Prolific, Sona Systems, CloudResearch Connect and Qualtrics.
Cite and describe
Participants completed the Similarity Arrangement Task in a web browser (ConductCognition task version 1.0.0, scoring version 1.0.0; Kriegeskorte N, Mur M, 2012; Goldstone R, 1994; Hout MC, Goldinger SD, Ferguson RW, 2013), with the standard settings (boards: 6). The main score was kind fit (spearman rank correlation between the 120 distances and the pictures' scene kinds: 0 for one kind, 1 for two natural or two built kinds, 2 for natural against built).
ConductCognition versions: task version 1.0.0, scoring version 1.0.0. Every export records the versions each session used, for a methods section.
- Kriegeskorte, N., & Mur, M. (2012). Inverse MDS: Inferring dissimilarity structure from multiple item arrangements. Frontiers in Psychology, 3, 245. https://doi.org/10.3389/fpsyg.2012.00245Dissimilarities estimated from arrangements of subsets of items, with the next subsets chosen to firm up the weakest evidence.
- Goldstone, R. (1994). An efficient method for obtaining similarity data. Behavior Research Methods, Instruments, & Computers, 26(4), 381-386. https://doi.org/10.3758/BF03204653The spatial arrangement of items on a screen as a way to collect similarity data.
- Hout, M. C., Goldinger, S. D., & Ferguson, R. W. (2013). The versatility of SpAM: A fast, efficient, spatial method of data collection for multidimensional scaling. Journal of Experimental Psychology: General, 142(1), 256-281. https://doi.org/10.1037/a0028860Similarity ratings from moving many stimuli around a screen, compared with pairwise ratings.
- Mur, M., Meys, M., Bodurka, J., Goebel, R., Bandettini, P., & Kriegeskorte, N. (2013). Human object-similarity judgments reflect and transcend the primate-IT object representation. Frontiers in Psychology, 4, 128. https://doi.org/10.3389/fpsyg.2013.00128Similarity judgments compared with brain activity patterns and models, with categorical divisions such as natural against man-made.
Source papers
- Kriegeskorte N, Mur M (2012). Inverse MDS: Inferring dissimilarity structure from multiple item arrangements. Frontiers in Psychology, 3:245.Paradigm source, Adults
Questions
How long does the Similarity Arrangement Task take?
About 6 to 10 minutes, as listed in the test library.
What device does a participant need?
Untimed test: runs on desktops, laptops, tablets and phones. The browser must be Chrome, Edge, Firefox or Safari.
What scores does it produce?
Kind Fit, Natural or Built Fit, Consistency, Study Agreement, Pairs in the Agreement, Comparison People, Boards, Planned Boards, Pairs on Two Boards, Weakest Evidence, Arranging Time and Moves. Each session is also marked valid, needs review or invalid, with the reason.
How widely is the Similarity Arrangement Task used in research?
37 papers from 2021 to 2025 name it in their title or abstract, up 61% compared with 2016 to 2020. That ranks it 519 of 711 test families in the ConductCognition test census (use grade D). Source: ConductCognition test census 0.58.0, counted 16 November 2026 from OpenAlex and ClinicalTrials.gov.
How much reliability evidence does the Similarity Arrangement Task have?
In the published research, 2 papers report its test-retest reliability and 0 registered clinical studies use it as an outcome (evidence grade C in the ConductCognition test census).
Does it report a percentile?
No. Scores and quality flags only.
Which settings can a researcher change?
Boards (3 to 8). Settings can be changed on yearly plans; free and pay-as-you-go studies use the standard settings.
Which languages can participants use?
Participants can take this test in English, Spanish, French, German, Italian, Portuguese (Brazil), Chinese (Simplified) and Japanese. English is on every plan, and the other languages come with yearly plans. Have a native speaker read the machine-translated text before launch.
Is this a clinical test?
No. ConductCognition is for research use only. It runs, scores and exports the test; clinical interpretation is outside the platform.
Every test: the full test list.
Run this test in your next study
Start free with 10 free participants on any test, then use participant credits or a yearly plan.