Episodic Memory
Mnemonic Similarity Task
Also called: mnemonic similarity test, MST, behavioral pattern separation task, pattern separation task, lure discrimination task
Measure how well people tell a picture they saw from one that only looks like it, with emoji pictures sorted as old, similar or new.
7-10 minUntimed
Free to start: 10 free participants per account, then $0.99 per participant for academic research, or any yearly plan. Preview any test free after you sign up.
- Papers, 2021 to 2025
- 195
- Evidence grade
- C
- Registered clinical studies
- 62
What it measures
Measures how well people tell a picture they saw from one that only looks like it. Participants judge pictures as indoors or outdoors, then sort a second set as old, similar or new. The pictures are emoji from one freely licensed set.
Constructs
- Pattern separation
- Recognition memory
- Mnemonic discrimination
- Incidental encoding
Research uses
- Memory and aging research
- Hippocampal function research
- Within-study group comparison
How the paradigm works
The Mnemonic Similarity Task measures how well people tell a picture they saw from one that only looks like it. In the study phase, 60 pictures appear one at a time for 2 seconds each with a 0.5 second gap, and participants say whether each belongs indoors or outdoors; nothing is said about memory. A memory test follows at once. It shows 60 pictures: a third are the same as studied pictures, a third are look-alikes of studied pictures and a third are new. Participants sort each one as Old, Similar or New. Each test picture shows for 2 seconds and the answers stay on screen for up to 5 seconds, followed by a 0.5 second gap. The procedure follows Stark and colleagues (2013), and the answers that stay after the picture leaves and the guided practice follow Stark and colleagues (2023). Telling a look-alike from the picture studied is thought to draw on pattern separation, and brain imaging work ties it to the hippocampus, in particular the dentate gyrus and CA3 (Kirwan and Stark, 2007; Yassa and colleagues, 2011).
More about the paradigm
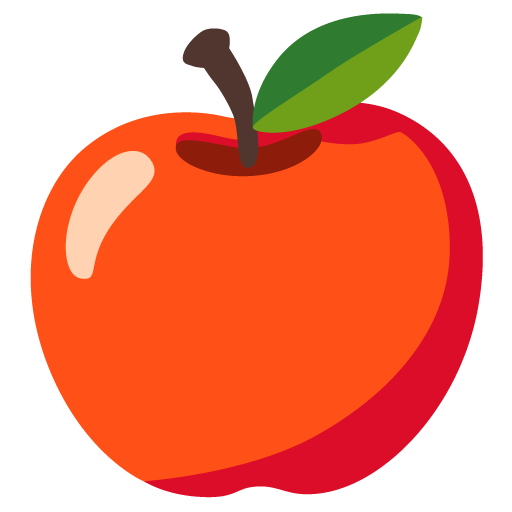
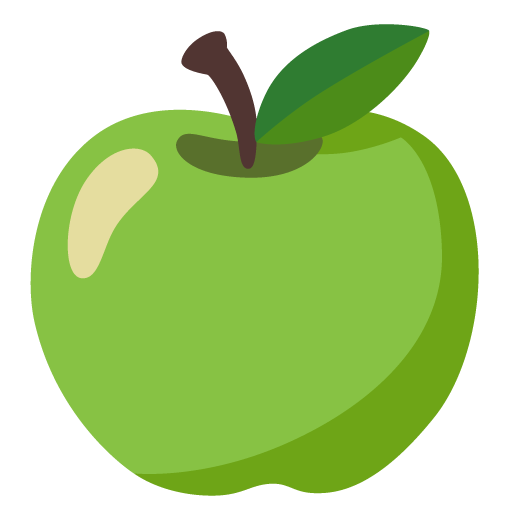
The pictures are emoji: 110 pictures of objects, animals, plants, food and vehicles from Noto Emoji, a freely licensed set, shown as the same image files on every device in place of the photographs of the lab task. There are no people, hands, flags, signs or text, no alcohol or weapons and nothing violent or offensive. The pool holds 28 look-alike pairs and 54 single pictures, chosen and paired by a stated rule for this task. A close pair shows one object in two colors or states, such as a red and a green apple, and a wider pair shows two objects of one kind, such as a tiger and a leopard. The session's seed draws 10 close and 10 wider pairs and which picture of each is studied, and fills the other roles from the pool. Each session studies 20 pictures that repeat, 20 that are followed by a look-alike and 20 that are not tested, and the test adds 20 new pictures. Four practice pictures open the study phase. Six practice test pictures with feedback follow the study list, and a look-alike's feedback shows it beside the picture studied. Researchers can set 36, 48 or 60 study pictures, 2 to 5 seconds for each study picture and 2 to 10 seconds to answer a test picture.
The primary score is the lure discrimination index: the rate of Similar for look-alikes minus the rate of Similar for new pictures. The recognition score is the rate of Old for repeats minus the rate of Old for new pictures. The rate of each answer for each picture type is reported, along with the index for close and for wider look-alikes. Rates are over the pictures answered. The published studies use photographs, so these scores are not comparable with norms from those studies. Scores support research and do not diagnose.
Scores
- Lure Discrimination Indexscore
- Rate of Similar for look-alikes minus the rate of Similar for new pictures.
- Higher is better
- Recognition Scorescore
- Rate of Old for repeats minus the rate of Old for new pictures.
- Higher is better. A score under 0.5 is flagged for review
- Old Rate, Repeats%
- Share of answered repeats sorted Old.
- Higher is better
- Similar Rate, Repeats%
- Share of answered repeats sorted Similar.
- Context for the scores
- New Rate, Repeats%
- Share of answered repeats sorted New.
- Context for the scores
- Old Rate, Look-Alikes%
- Share of answered look-alikes sorted Old.
- Context for the scores
- Similar Rate, Look-Alikes%
- Share of answered look-alikes sorted Similar.
- Higher is better
- New Rate, Look-Alikes%
- Share of answered look-alikes sorted New.
- Context for the scores
- Old Rate, New Pictures%
- Share of answered new pictures sorted Old.
- Context for the scores
- Similar Rate, New Pictures%
- Share of answered new pictures sorted Similar.
- Context for the scores
- New Rate, New Pictures%
- Share of answered new pictures sorted New.
- Higher is better
- Lure Discrimination, Close Pairsscore
- The index for look-alikes from close pairs.
- Higher is better
- Lure Discrimination, Wider Pairsscore
- The index for look-alikes from wider pairs.
- Higher is better
- Median Response Timems
- Median time from the picture to an answer, over answers at or after 100 ms.
- Context for the scores
- Test Answer Rate%
- Share of test pictures answered.
- Under 0.75 invalidates the session
- Study Answer Rate%
- Share of study pictures answered.
- Under 0.5 is flagged for review
- Anticipationscount
- Test answers under 100 ms. They still count as answers.
- Context for the scores
- Test Pictures Recordedcount
- Test pictures recorded in the run.
- Fewer than 18 invalidates the session
- Test Pictures Plannedcount
- Test pictures the settings planned.
- Fewer recorded than planned is flagged for review
Use and evidence
195 papers from 2021 to 2025 name this task in their title or abstract, up 40% compared with 2016 to 2020. That ranks it 125 of 395 test families in our census. See the counts for every test.
Show the numbers
| Year | Papers |
|---|---|
| 2025 | 54 |
| 2024 | 41 |
| 2023 | 36 |
| 2022 | 32 |
| 2021 | 32 |
| 2020 | 36 |
| 2019 | 25 |
| 2018 | 34 |
| 2017 | 31 |
| 2016 | 13 |
| 2015 | 18 |
| 2014 | 19 |
| 2013 | 8 |
| 2012 | 5 |
| 2011 | 0 |
| 2010 | 1 |
| 2009 | 0 |
| 2008 | 2 |
| 2007 | 1 |
| 2006 | 1 |
| 2005 | 0 |
| 2004 | 0 |
| 2003 | 0 |
| 2002 | 0 |
| 2001 | 0 |
| 2000 | 0 |
Use grade C
100 to 299 papers from 2021 to 2025.
Evidence grade C
At least 2 test-retest papers, 30 reliability or validity papers or 3 registered clinical studies.
- Papers on test-retest reliability
- 4
- Papers on reliability or validity
- 21
- Registered clinical studies using it as an outcome
- 62
How the grades work
Use: A is 1,000 or more papers from 2021 to 2025, B 300 to 999, C 100 to 299, D 30 to 99 and E fewer than 30. Evidence: A means at least 25 papers report its test-retest reliability and at least 25 registered clinical studies use it as an outcome; B, at least 8 test-retest papers, and either 5 registered clinical studies or 150 reliability or validity papers; C, at least 2 test-retest papers, 30 reliability or validity papers or 3 registered clinical studies; D, little published measurement evidence found. The counts measure use. They include every paper that names the task in its title or abstract. Grades describe the published research on this task, not ConductCognition's version of it.
Source: ConductCognition test census 0.14.0, counted 31 October 2026 from OpenAlex and ClinicalTrials.gov.
Task design
The trial sequence as the test runs in ConductCognition.
- Pictures
- 110 emoji from Noto Emoji, a freely licensed set, shown as the same image files on every device, up to 260 px wide. The device's emoji font is never used.
- Look-alikes
- 28 pairs: 14 close, one object in two colors or states, and 14 wider, two objects of one kind. The session's seed draws 10 of each and which picture of each pair is studied.
- Study
- 60 pictures (standard; 36 or 48), 2 seconds each (standard; 2 to 5) with a 0.5 second gap, judged indoors or outdoors. Nothing is said about memory.
- Test
- Right after the study list, 60 pictures: a third repeats, a third look-alikes of studied pictures and a third new, with no more than 4 of one type in a row. The other 20 study pictures are not tested.
- Answers
- Old, Similar or New, on three buttons side by side or the keys 1, 2 and 3.
- Timing
- Each test picture shows for 2 seconds, the answers stay on screen until 5 seconds (standard; 2 to 10), and a 0.5 second gap follows.
- Practice
- 4 study pictures before the list, then 6 test pictures with feedback after it. A look-alike's feedback shows it beside the picture studied.
- Selection rule
- Object, animal, plant, food and vehicle emoji, looked at one by one. No people, hands, flags, signs or text, no alcohol or weapons, and nothing violent or offensive. The pairs come from no published picture set.
The pictures are emoji, not the photographs of the published studies, so scores are not comparable with norms from those studies.
Quality checks
Each session is marked valid, needs review or invalid, with the reason, before you see its scores.
Scored rows: mnemonic_similarity_test from the scored run, one of three answers for each picture (chance 1 in 3, each picture type a third of the test). Below chance invalidates and not above chance is flagged. One answer on 90% of answers invalidates when accuracy is not above chance. Answers under 200 ms on at least half the trials invalidate. Fewer than 18 recorded test trials (six of each type) or fewer than 75% of test pictures answered invalidate. Fewer trials than planned, fewer than 50% of study pictures answered or a recognition score under 0.5 flag the session and withhold the percentile. A hidden tab withholds the percentile.
Why these rules
Accuracy significantly below chance (one-sided exact test, p < .05) cannot come from guessing; it means the response mapping was reversed or the task was not followed (Slick, Sherman and Iverson 1999 treat below-chance forced-choice performance as definite response bias). Chance-level accuracy can be a real result in impaired participants, so it is only flagged. One option on at least 90% of answered trials, when the correct options are balanced and accuracy is not above chance, means the answers did not depend on the items (the task counterpart of long-string responding in surveys; Curran 2016). An answer under 200 ms is faster than a simple visual reaction, so it cannot reflect the item. Following response-time effort screening for untimed tests (Wise and Kong 2005), the session is invalid only when at least half the answers are that fast. The rates need answers: under 75% of test pictures answered is the line of the platform's timed-test rule, and six pictures of each type is the fewest that leave a rate that can move in steps smaller than a sixth. A study picture with no answer may not have been looked at, and a person who skipped half of them has not studied the list, so the session is flagged. Stark and colleagues (2023) filtered online participants with a recognition score of at least 0.5 to find those not actively engaged, and report about 0.6 as typical of older adults with mild cognitive impairment, so a lower score more likely means the task was not followed; real impairment can also reach it, so it is flagged and not invalidated. A hidden tab lets the study, delay or response timers run without the participant, so a percentile is withheld after one.
Running this test
Settings you can change
| Setting | Standard | Allowed |
|---|---|---|
| Study pictures | 60 (standard) | 36, 48, 60 (standard) |
| Time per study picture (seconds) | 2 | 2 to 5 |
| Time to answer in the test (seconds) | 5 | 2 to 10 |
Yearly plans can change settings within these limits. Free and pay-as-you-go studies use the standard settings.
Need a setting this test does not have?
Devices and languages
- Untimed test: runs on desktops, laptops, tablets and phones. Participant devices
- Languages: English, Spanish, French, German, Italian, Portuguese (Brazil), Chinese (Simplified) and Japanese.
- Available on: Every plan, including the free plan.
- Recruiting online? See the setup guides for Prolific, Sona Systems, CloudResearch Connect and Qualtrics.
Cite and describe
Participants completed the Mnemonic Similarity Task in a web browser (ConductCognition task version 1.0.0, scoring version 1.0.0; Stark, Yassa, Lacy & Stark, 2013; Stark, Kirwan & Stark, 2019), with the standard settings (study pictures: 60; time per study picture (seconds): 2; time to answer in the test (seconds): 5). The main score was lure discrimination index (rate of Similar for look-alikes minus the rate of Similar for new pictures).
ConductCognition versions: task version 1.0.0, scoring version 1.0.0. Every export records the versions each session used, for a methods section.
- Stark, S. M., Yassa, M. A., Lacy, J. W., & Stark, C. E. L. (2013). A task to assess behavioral pattern separation (BPS) in humans: Data from healthy aging and mild cognitive impairment. Neuropsychologia, 51(12), 2442-2449. https://doi.org/10.1016/j.neuropsychologia.2012.12.014The procedure, the timing and the two scores.
- Stark, S. M., Kirwan, C. B., & Stark, C. E. L. (2019). Mnemonic Similarity Task: A tool for assessing hippocampal integrity. Trends in Cognitive Sciences, 23(11), 938-951. https://doi.org/10.1016/j.tics.2019.08.003Review of the task and what it measures.
- Stark, C. E. L., Noche, J. A., Ebersberger, J. R., Mayer, L., & Stark, S. M. (2023). Optimizing the mnemonic similarity task for efficient, widespread use. Frontiers in Behavioral Neuroscience, 17, 1080366. https://doi.org/10.3389/fnbeh.2023.1080366Answers that stay after the picture leaves, guided practice and the recognition filter.
- Kirwan, C. B., & Stark, C. E. L. (2007). Overcoming interference: An fMRI investigation of pattern separation in the medial temporal lobe. Learning & Memory, 14(9), 625-633. https://doi.org/10.1101/lm.663507Pattern separation in brain imaging.
- Yassa, M. A., Lacy, J. W., Stark, S. M., Albert, M. S., Gallagher, M., & Stark, C. E. L. (2011). Pattern separation deficits associated with increased hippocampal CA3 and dentate gyrus activity in nondemented older adults. Hippocampus, 21(9), 968-979. https://doi.org/10.1002/hipo.20808Aging, the dentate gyrus and CA3.
Source papers
- Stark SM, Yassa MA, Lacy JW, Stark CEL (2013). A task to assess behavioral pattern separation (BPS) in humans: data from healthy aging and mild cognitive impairment. Neuropsychologia, 51(12):2442-2449.Paradigm source, Adults
- Stark SM, Kirwan CB, Stark CEL (2019). Mnemonic Similarity Task: a tool for assessing hippocampal integrity. Trends in Cognitive Sciences, 23(11):938-951.Paradigm source, Adults
- Stark CEL, Noche JA, Ebersberger JR, Mayer L, Stark SM (2023). Optimizing the mnemonic similarity task for efficient, widespread use. Frontiers in Behavioral Neuroscience, 17:1080366.Paradigm source, Adults
- Kirwan CB, Stark CEL (2007). Overcoming interference: an fMRI investigation of pattern separation in the medial temporal lobe. Learning & Memory, 14(9):625-633.Paradigm source, Adults
- Yassa MA, Lacy JW, Stark SM, Albert MS, Gallagher M, Stark CEL (2011). Pattern separation deficits associated with increased hippocampal CA3 and dentate gyrus activity in nondemented older adults. Hippocampus, 21(9):968-979.Paradigm source, Older adults
Questions
How long does the Mnemonic Similarity Task take?
About 7 to 10 minutes, as listed in the test library.
What device does a participant need?
Untimed test: runs on desktops, laptops, tablets and phones. The browser must be Chrome, Edge, Firefox or Safari.
What scores does it produce?
Lure Discrimination Index, Recognition Score, Old Rate, Repeats, Similar Rate, Repeats, New Rate, Repeats, Old Rate, Look-Alikes, Similar Rate, Look-Alikes, New Rate, Look-Alikes, Old Rate, New Pictures, Similar Rate, New Pictures, New Rate, New Pictures, Lure Discrimination, Close Pairs, Lure Discrimination, Wider Pairs, Median Response Time, Test Answer Rate, Study Answer Rate, Anticipations, Test Pictures Recorded and Test Pictures Planned. Each session is also marked valid, needs review or invalid, with the reason.
How widely is the Mnemonic Similarity Task used in research?
195 papers from 2021 to 2025 name it in their title or abstract, up 40% compared with 2016 to 2020. That ranks it 125 of 395 test families in the ConductCognition test census (use grade C). Source: ConductCognition test census 0.14.0, counted 31 October 2026 from OpenAlex and ClinicalTrials.gov.
How much reliability evidence does the Mnemonic Similarity Task have?
In the published research, 4 papers report its test-retest reliability and 62 registered clinical studies use it as an outcome (evidence grade C in the ConductCognition test census).
Which settings can a researcher change?
Study pictures (36, 48, 60 (standard)), time per study picture (seconds) (2 to 5) and time to answer in the test (seconds) (2 to 10). Settings can be changed on yearly plans; free and pay-as-you-go studies use the standard settings.
Which languages can participants use?
Participants can take this test in English, Spanish, French, German, Italian, Portuguese (Brazil), Chinese (Simplified) and Japanese. English is on every plan, and the other languages come with yearly plans. Have a native speaker read the machine-translated text before launch.
Is this a clinical test?
No. ConductCognition is for research use only. It runs, scores and exports the test; clinical interpretation is outside the platform.
Every test: the full test list.
Run this test in your next study
Start free with 10 free participants on any test, then use participant credits or a yearly plan.